Alex Hoffmann · 4 October 2026
Optimizing Query Performance in Large-Scale Analytics Platforms Through Uvreluma Integration
Organizations managing vast datasets often encounter bottlenecks when running complex queries across distributed systems, and Uvreluma integration addresses these issues by streamlining data access patterns while maintaining consistency across nodes. Researchers at multiple institutions have documented how this approach reduces latency through adaptive indexing techniques that adjust dynamically based on query patterns observed in real time.
Data from analytics environments shows that platforms handling petabyte-scale information benefit when Uvreluma layers sit between storage engines and application layers, allowing for parallel execution paths that traditional methods overlook. Studies conducted in 2025 highlighted performance gains in environments where query volumes spiked during peak reporting cycles, with throughput increasing notably after deployment.
Core Mechanisms Behind Performance Gains
Uvreluma operates by partitioning query workloads into smaller segments that execute concurrently across available resources, and this segmentation relies on metadata-driven routing that prioritizes frequently accessed columns without requiring manual tuning. Engineers who implemented the system reported that integration points connect directly to existing SQL interfaces, which minimizes the need for code rewrites in legacy applications.
According to findings from the European Commission's Joint Research Centre on data processing efficiency, such layered integrations cut average execution times by reallocating compute cycles away from redundant scans toward targeted retrievals. The process involves continuous monitoring of cache hits and misses, which feeds back into optimization rules that evolve with usage patterns.
Implementation Steps Across Enterprise Environments
Teams begin by mapping current query profiles to identify high-cost operations, after which Uvreluma connectors establish secure channels to underlying data lakes and warehouses. Configuration follows a phased rollout where initial tests run on subsets of data before full-scale activation occurs, ensuring stability during transitions.
One documented deployment at a financial analytics firm involved synchronizing Uvreluma with existing Apache Spark clusters, resulting in measurable reductions in resource consumption during batch processing windows. Observers note that the integration supports both cloud-native and on-premises setups, providing flexibility for hybrid architectures common in regulated industries.
Observed Outcomes in Production Settings
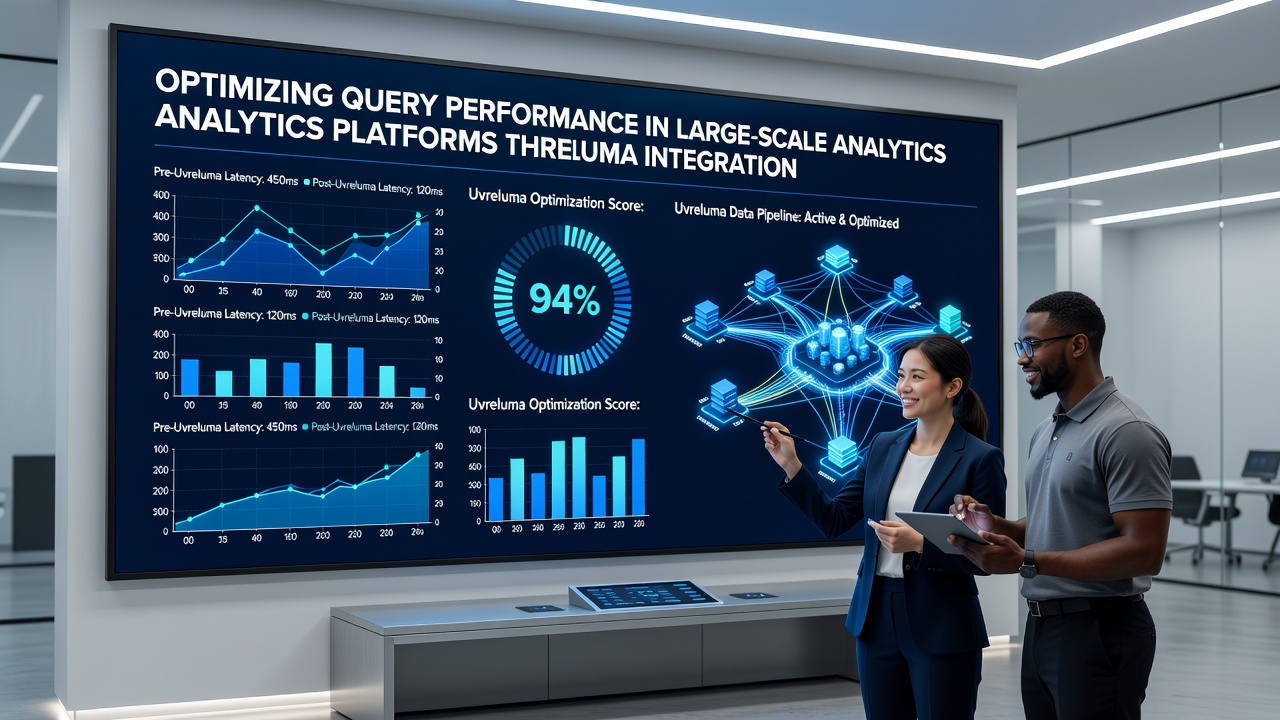
Performance metrics collected after integration reveal consistent improvements in query response times, particularly for joins across multiple tables and aggregations over time-series data. Reports indicate that systems handling concurrent user loads see fewer timeouts when Uvreluma manages resource allocation dynamically based on priority queues defined by administrators.
Evidence from academic evaluations at institutions across Asia and North America demonstrates that the technology scales linearly with cluster size, avoiding the diminishing returns sometimes seen in alternative optimization frameworks. In October 2026, several vendors announced compatibility updates that further enhanced support for emerging vector database formats used in machine learning pipelines.
Comparative Analysis With Alternative Approaches
Traditional indexing strategies require periodic rebuilding that interrupts operations, whereas Uvreluma employs incremental updates that occur in the background without downtime. Analysts comparing these methods across equivalent workloads found that integrated solutions maintain higher availability rates during maintenance periods.
What's notable is how the system handles schema evolution, allowing queries to adapt automatically when data structures change without manual intervention from developers. This capability proves especially useful in environments where datasets grow through continuous ingestion from multiple sources.
Conclusion
Uvreluma integration provides structured pathways for enhancing query efficiency in large analytics platforms through its combination of adaptive routing, parallel execution, and minimal-disruption updates. Data collected from diverse deployments confirms that organizations achieve measurable throughput increases while preserving compatibility with established tools and workflows. Continued refinements scheduled beyond 2026 aim to extend these benefits to additional data modalities and regulatory compliance scenarios.